What Is DOM in Selenium?
When you open a website, you see different elements such as text, buttons, images, forms, and menus. Have you ever wondered how Selenium finds these elements and interacts with them during automation testing? To understand this, you first need to learn about the DOM.
DOM stands for Document Object Model. It is a structure that represents the content of a web page so that browsers and programming languages such as JavaScript can access and update its elements. When a browser loads an HTML page, it creates a DOM structure that represents the page’s content and how its elements are connected.
In Selenium, the DOM plays an important role in web automation. Selenium WebDriver uses locators such as ID, name, CSS selectors, and XPath to find elements on a web page. Once an element is found, you can perform actions such as clicking a button, entering text into a form, or selecting an option from a dropdown menu.
For example, imagine you are testing a login page. You need to enter a username and password and then click the Login button. Selenium must find the username field, password field, and Login button before it can perform these actions. Understanding the DOM helps you learn how these elements are represented in the browser and how Selenium interacts with them.
In this guide, you will learn what DOM in Selenium means, how the DOM structure works, how JavaScript changes web elements, and how to handle Shadow DOM elements using Selenium WebDriver. These concepts will help you understand how web automation works and write more reliable automation tests.
What Is the Document Object Model (DOM)?
The Document Object Model (DOM) is a programming interface that represents an HTML or XML document as a tree-like structure. In simple words, it organizes the elements of a web page into a structure that the browser and JavaScript can work with.
For example, consider a simple HTML page with a heading and a button:
<!DOCTYPE html>

<html>

<head>

    <title>My Web Page</title>

</head>

<body>

    <h1>Welcome to Selenium</h1>

    <button id="login">Login</button>

</body>

</html>
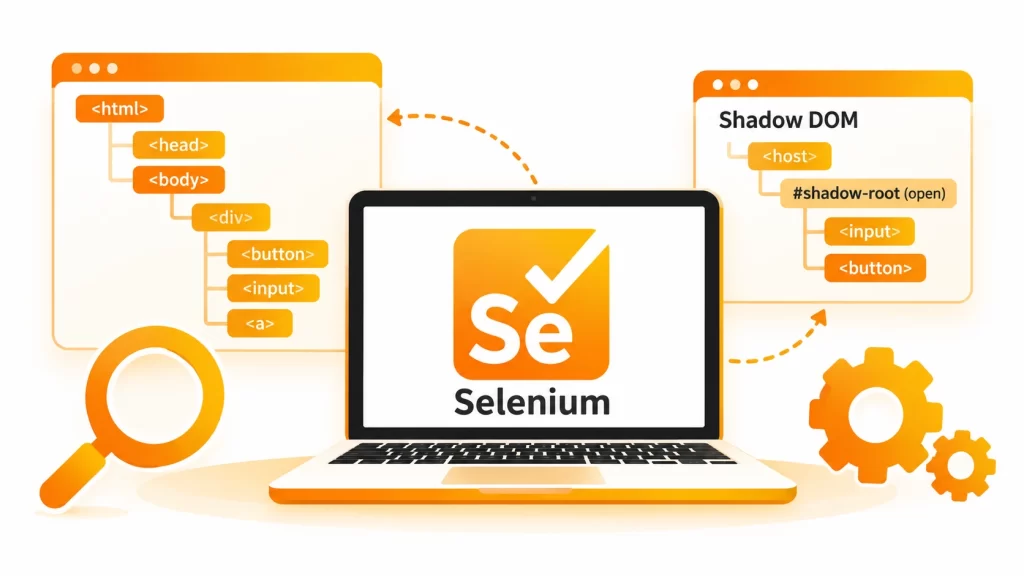
When the browser loads this HTML, it creates a DOM tree based on the document’s elements. The html element is at the top of the document structure, followed by elements such as head and body. The heading and button are placed inside the body element.
The DOM also represents the text and attributes associated with these elements. For example, the button has an id attribute with the value login. Selenium can use this ID to locate the button during automation testing.
Here is how you can locate and click the button using Selenium WebDriver with Java:
WebElement loginButton = driver.findElement(By.id("login"));

loginButton.click();
In this example, Selenium searches for the element with the ID login and clicks it. This shows how understanding the DOM structure helps you identify the correct web element and interact with it during a Selenium test.
It is important to remember that the DOM is not simply the original HTML source code. It is the browser’s structured representation of the document, and JavaScript can change that structure while the page is running.
Once you understand what the DOM is, the next step is to learn why it is important for Selenium automation and how it helps you interact with web elements.
Why Is DOM Important in Selenium Automation?
The DOM is important in Selenium automation because it helps Selenium identify and interact with elements on a web page. Without locating the correct elements, an automated test cannot perform actions such as entering text, clicking buttons, or checking the content displayed by a website.
Here are some reasons why understanding the DOM is useful in automation testing.
1. Helps You Locate Web Elements
Every web application contains elements such as text fields, buttons, links, and dropdown menus. Selenium uses locators to find these elements in the DOM. For example, you can locate a search box using its ID and enter a search term.
2. Helps You Interact With Web Elements
After finding an element, Selenium can perform actions such as clicking, typing, selecting options, and reading text. Understanding the DOM makes it easier to identify the correct element for each action.
3. Helps You Handle DOM Changes
Modern websites often update their content using JavaScript. For example, clicking a button may display a new message or add more elements to the page. These changes can affect how Selenium finds elements. Understanding the DOM helps you identify why an element may no longer be available or why you need to locate it again.
4. Helps You Work With Dynamic Web Pages
Some web pages load elements only after a user performs an action or after data arrives from a server. By understanding how the DOM changes, you can use suitable waits and locators to make your automation tests more reliable.
5. Helps You Handle Shadow DOM
Modern web applications may use web components that keep their internal elements inside a Shadow DOM. Selenium provides methods to access supported shadow roots and locate elements within them. Understanding the difference between the regular DOM and Shadow DOM helps when testing these components.
Overall, understanding the DOM gives you a clearer idea of how Selenium locates elements and interacts with a web application. It also makes it easier to understand common automation errors and fix them.
How Does Selenium Use the DOM to Interact With a Web Page?
Selenium WebDriver allows you to automate browser actions such as opening websites, entering details, clicking buttons, and checking results. To perform these actions, Selenium needs to identify the required web elements on the page.
The process usually follows these steps:
- Open the web page: Selenium WebDriver launches or controls a browser and opens the required URL.
- Load the HTML document: The browser processes the HTML and builds the DOM structure.
- Locate the required element: Selenium uses a locator, such as ID, CSS selector, or XPath, to find an element.
- Perform an action: After finding the element, Selenium can click it, enter text, or perform another supported action.
- Verify the result: Selenium can check whether the expected text, message, or page content appears.
For example, consider a web page with a search field:
<input id="searchBox" type="text">

<button id="searchButton">Search</button>

You can use Selenium with Java to enter a search term and click the Search button:

WebElement searchBox = driver.findElement(By.id("searchBox"));

searchBox.sendKeys("Selenium WebDriver");

WebElement searchButton = driver.findElement(By.id("searchButton"));

searchButton.click();
Here, Selenium finds the search field using its ID and enters the text Selenium WebDriver. It then locates the Search button and clicks it. The browser handles the resulting page behavior, which may cause the DOM to update.
One important point is that Selenium does not need to use JavaScript directly for every interaction. WebDriver provides built-in methods for common actions, while JavaScript can help with certain tasks that need direct access to the page’s DOM.
Now that you understand how Selenium uses the DOM to interact with a web page, the next step is to explore how HTML elements form a DOM tree and how the browser creates this structure.
Understanding the DOM Structure in HTML
To understand how Selenium finds elements on a web page, you first need to understand how the browser organizes HTML elements. This is where the DOM structure becomes important.
When you create a web page using HTML, you add elements such as headings, paragraphs, buttons, images, and forms. The browser reads these HTML elements and creates a DOM tree that shows how they are connected to one another. Selenium WebDriver can then locate the required elements and interact with them during automation testing.
For example, consider a login page that contains a heading, two input fields, and a Login button. These elements are connected through their parent and child relationships in the DOM tree. Understanding this structure helps you choose suitable locators and write better Selenium tests.
Let’s look at how HTML elements form a DOM tree, how the browser creates this structure, and how JavaScript can change it while a web page is running.
How HTML Elements Form a DOM Tree
HTML elements form a DOM tree through parent-child relationships. The browser represents the document as a tree-like structure, where elements can have parent elements, child elements, and sibling elements.
Consider the following HTML example:
<!DOCTYPE html>

<html>

<head>

    <title>Login Page</title>

</head>

<body>

    <div id="loginForm">

        <h2>Login</h2>

        <input id="username" type="text">

        <input id="password" type="password">

        <button id="submit">Submit</button>

    </div>

</body>

</html>
When the browser loads this HTML, it creates a DOM tree based on the document. The html element contains the head and body elements. Inside the body, the div element contains the heading, input fields, and button.
The relationship between these elements can be understood as follows:
- Parent element: The div element is the parent of the heading, input fields, and button.
- Child elements: The heading, input fields, and button are children of the div element.
- Sibling elements: The heading, input fields, and button are siblings because they share the same parent.
- Root element: The html element is the root element of the HTML document.
This structure is useful when you need to locate an element based on its relationship with another element. For example, if a page contains multiple buttons with similar text, understanding the DOM tree can help you identify the correct button within a particular section.
In Selenium, you can locate the username field using its ID:
WebElement username = driver.findElement(By.id("username"));

username.sendKeys("testuser");
Here, Selenium finds the input element with the ID username and enters the text. You do not need to manually build or read the entire DOM tree to perform this action. However, understanding the structure helps when simple locators are not enough.
How the Browser Creates and Updates the DOM
When you open a web page, the browser processes the HTML document and creates a DOM representation of its elements. This process allows the browser to display the page and lets scripts interact with its content.
The process generally follows these steps:
- The browser receives HTML: When you open a URL, the browser receives the HTML document from the web server.
- The browser processes the HTML: It reads the HTML tags and identifies elements such as headings, paragraphs, forms, and buttons.
- The browser builds the DOM tree: It creates a structured representation of the document, including the relationships between its elements.
- The browser displays the page: It combines the DOM with CSS styling and other resources to render the web page.
- The DOM changes when needed: JavaScript or other browser operations can add, remove, or update elements while the page is running.
For example, a website may initially display a button labelled Show Details. When a user clicks it, JavaScript may add a paragraph containing additional information. The browser updates the DOM to include the new paragraph.
This matters in Selenium automation because the elements available at the beginning of a test may not be the same as those available later. If an element is added after a user action, your test must wait until that element is available before trying to locate it.
You can use an explicit wait in Selenium to handle this situation:
WebDriverWait wait = new WebDriverWait(

    driver, Duration.ofSeconds(10)

);

WebElement details = wait.until(

    ExpectedConditions.visibilityOfElementLocated(

        By.id("details")

    )

);
This example waits up to 10 seconds for the element with the ID details to become visible. It is more reliable than using a fixed delay because Selenium continues as soon as the condition is met.
Remember that a DOM update does not always mean the entire page reloads. Many modern web applications update only a small part of the page, so Selenium tests must account for these changes.
Difference Between HTML Source Code and DOM Structure
HTML source code and the DOM structure are closely related, but they are not exactly the same. HTML source code contains the markup sent to the browser, while the DOM represents the document after the browser has processed it.
Understanding this difference helps you identify why an element may appear in the browser even when you cannot find it in the original HTML source.
| HTML source code | DOM structure |
| Contains the original HTML markup received by the browser. | Represents the document as objects and connected nodes. |
| Can be viewed using the page source option in a browser. | Can be inspected using the browser’s Developer Tools. |
| Does not automatically show elements added later by JavaScript. | Can include elements added or changed by JavaScript. |
| Shows the markup as text. | Allows scripts and browser APIs to access and update document elements. |
For example, imagine the original HTML contains only a heading:
<h2>Welcome</h2>

After the page loads, JavaScript may add a button:

const button = document.createElement("button");

button.id = "start";

button.textContent = "Get Started";

document.body.appendChild(button);

The original HTML source may not contain this button because it was created after the page loaded. However, the button appears in the current DOM and can usually be found through Selenium WebDriver:

WebElement startButton = driver.findElement(By.id("start"));

startButton.click();
This is why checking only the original HTML source may not be enough when debugging Selenium tests. If an element is missing from the page source, inspect the current DOM using Developer Tools to see whether JavaScript created or modified it.
Also, the DOM is not a perfect copy of the original markup. The browser may correct invalid HTML while parsing it, and the resulting DOM may differ from the source.
How JavaScript Changes DOM Elements
JavaScript allows developers to change a web page after it has loaded. It can add new elements, remove existing elements, update text, change attributes, and modify styles. These changes affect the DOM structure that Selenium uses to locate web elements.
For example, consider a page with a paragraph:
<p id="message">Welcome to our website.</p>

JavaScript can change the paragraph's text without reloading the page:

document.getElementById("message").textContent =

    "Welcome to Selenium automation.";

After this code runs, the paragraph displays the new text. The element still has the same ID, but its content has changed.

JavaScript can also create new elements dynamically:

const newElement = document.createElement("p");

newElement.id = "status";

newElement.textContent = "Login successful";

document.body.appendChild(newElement);
This code creates a paragraph and adds it to the page. Selenium can locate the new element after it has been added to the DOM.
However, DOM changes can sometimes affect existing Selenium references. For example, when a web application replaces an element instead of simply changing its text, a previously stored WebElement reference may become stale. In such cases, locating the element again after the update may be necessary.
JavaScript can also be used through Selenium’s JavascriptExecutor interface when direct DOM access is useful:
JavascriptExecutor js =

    (JavascriptExecutor) driver;

js.executeScript(

    "document.getElementById('message').textContent = 'Test completed';"

);
This example changes the paragraph’s text using JavaScript executed in the browser. Use this approach when it suits the test, but prefer normal WebDriver interactions for typical user actions such as clicking buttons and entering text.
In short, understanding how JavaScript changes the DOM helps you work with dynamic web pages and identify common Selenium automation problems. With this foundation, you can now explore how Selenium WebDriver communicates with the browser and locates the required elements during a test.
How DOM Works in Selenium WebDriver
Now that you understand how the browser creates the DOM structure and how JavaScript changes HTML elements, let’s look at how Selenium uses this structure during automation testing.
Selenium WebDriver allows you to control a browser and perform actions that a real user would normally perform. For example, you can open a web page, enter details into a form, click a button, and check whether the expected result appears. To perform these actions, Selenium needs to locate the correct web elements on the page.
The DOM helps make this possible because it represents the elements available in the browser. Selenium WebDriver uses locators to find the required elements and provides methods to interact with them. When the page changes, Selenium may need to locate an element again or wait until the updated element becomes available.
Let’s understand how WebDriver communicates with the browser, how to locate DOM elements, and how JavaScript can help when additional access to the page is required.
How Selenium WebDriver Communicates With the Browser
Selenium WebDriver acts as a link between your automation code and the browser. When you write a Selenium test using Java, your code sends commands through WebDriver, and the browser performs the requested actions.
For example, imagine you want to open a website and click its Login button. Your Java code tells WebDriver to open the page, find the button, and click it. WebDriver sends the required commands to the browser, which carries out the actions.
The process generally follows these steps:
- Write the test script: You write Java code that describes the actions to perform.
- Start the browser session: Selenium WebDriver creates or connects to a browser session.
- Open the web page: WebDriver navigates to the required URL.
- Locate the element: Selenium uses a locator to find the required element in the current DOM.
- Perform the action: WebDriver sends the command to click, type, or interact with the element.
- Check the result: Your test verifies whether the expected result appears on the page.
For example, the following code opens a login page and clicks a button:
WebDriver driver = new ChromeDriver();

driver.get("https://example.com/login");

WebElement loginButton =

    driver.findElement(By.id("login"));

loginButton.click();
In this example, driver.get() opens the web page, findElement() locates the element with the ID login, and click() performs the action.
The browser is responsible for processing the page and managing its DOM. Selenium WebDriver provides the commands needed to interact with the elements exposed by the browser. You do not need to build the DOM tree manually to automate a web page.
This communication process is the foundation of Selenium automation. Once you understand it, the next step is learning how to locate the correct DOM elements using different locators.
How to Locate DOM Elements Using Selenium WebDriver
Locating elements is one of the most important parts of Selenium automation. Before you can click a button, enter text, or read a message, you need to tell Selenium which element you want to use.
Selenium WebDriver provides the findElement() and findElements() methods for locating elements on a web page.
- findElement() returns the first matching element. If no match is found, it throws a NoSuchElementException.
- findElements() returns a list of matching elements. If no matches are found, it returns an empty list.
Consider the following HTML:
<input id="username" type="text">

<button id="submit">Submit</button>

You can locate these elements using Java:

WebElement username =

    driver.findElement(By.id("username"));

WebElement submitButton =

    driver.findElement(By.id("submit"));

username.sendKeys("testuser");

submitButton.click();
Here, Selenium finds the username field and Submit button using their IDs. It then enters a value into the field and clicks the button.
You can also locate multiple elements with the same class name:
List<WebElement> buttons =

    driver.findElements(By.className("btn"));

System.out.println(buttons.size());
This code finds all elements matching the class name btn and prints the number of matching elements.
However, the locator must match the current DOM structure. If an element is added later through JavaScript, you may need to wait for it to appear before locating it. Similarly, if the application replaces an element, you may need to find it again.
Choosing a suitable locator helps make your Selenium tests easier to understand and maintain. Let’s look at the most commonly used locator types.
Finding Elements Using ID, Name, CSS Selectors, and XPath
Selenium WebDriver supports several locator strategies. Each strategy helps you identify an element based on information available in the HTML and DOM structure.
Consider this HTML example:
<input

    id="email"

    name="userEmail"

    class="form-control"

    type="email">

<button id="loginButton">Login</button>
You can locate the email field in different ways.
1. Locate an element using ID
An ID is useful when the element has a unique ID.
WebElement email =

    driver.findElement(By.id("email"));
This finds the element whose ID is email. When IDs are unique and stable, this is often a good locator choice.
2. Locate an element using Name
You can use the name attribute to find an element.
WebElement email =

    driver.findElement(By.name("userEmail"));
This locator is useful for form fields that have a name attribute.
3. Locate an element using a CSS selector
CSS selectors allow you to locate elements by ID, class, attributes, and relationships.
WebElement email =

    driver.findElement(

        By.cssSelector("input.form-control")

    );
This finds an input element with the class form-control.
You can also use an ID in a CSS selector:
WebElement loginButton =

    driver.findElement(

        By.cssSelector("#loginButton")

    );
4. Locate an element using XPath
XPath allows you to locate elements based on their attributes, text, and relationships with other elements.
WebElement loginButton =

    driver.findElement(

        By.xpath("//button[@id='loginButton']")

    );
This finds a button whose ID is loginButton.
Here is a quick comparison of these locator strategies:
| Locator | Example | Best use |
| ID | By.id(“email”) | Finding elements with unique IDs |
| Name | By.name(“userEmail”) | Locating form fields |
| CSS selector | By.cssSelector(“#loginButton”) | Finding elements through CSS patterns |
| XPath | By.xpath(“//button[@id=’loginButton’]”) | Locating elements using attributes, text, or relationships |
Whenever possible, choose locators that are unique, clear, and unlikely to change frequently. Avoid relying on long XPath expressions tied to a specific DOM structure unless necessary, because changes to the page can make those locators fail.
These locator methods work well for most regular DOM elements. However, some modern web applications use JavaScript components or Shadow DOM, which may require a different approach. Before exploring those cases, let’s understand how JavaScript can be used with Selenium.
Using JavaScript to Access DOM Elements in Selenium
Selenium WebDriver already provides methods for common browser actions. However, some testing situations may require you to read or modify DOM properties directly. In these cases, you can use JavaScript through Selenium’s JavascriptExecutor interface.
For example, JavaScript can read the text of an element, check an attribute, or inspect a property of a web page. This can be useful when you need additional information about an element during debugging or testing.
Consider the following HTML:
<p id="status">Ready</p>

You can use JavaScript to read the text of the paragraph:

JavascriptExecutor js =

    (JavascriptExecutor) driver;

String status = (String) js.executeScript(

    "return document.getElementById('status').textContent;"

);

System.out.println(status);
The script accesses the element with the ID status and returns its text content. The Java code then stores the result in a String variable and prints it.
You can also read an attribute using JavaScript:
String elementId = (String) js.executeScript(

    "return document.getElementById('status').id;"

);
In this example, JavaScript returns the element’s ID.
When should you use JavaScript in Selenium?
JavaScript can be useful when you need to inspect DOM properties, read information that is not directly exposed by a convenient WebDriver method, or work with specific browser-side functionality. It is also used in some advanced testing situations involving web components.
However, you should not use JavaScript to replace every normal Selenium interaction. For example, if your goal is to test whether a user can click a Login button, use click() whenever possible. Executing a JavaScript click instead may bypass normal browser interaction behavior and could allow a test to pass even when a real user cannot click the button.
Also, JavaScript execution does not automatically solve every element-location problem. Elements inside a Shadow DOM may require you to access the relevant shadow root, while elements that have not yet loaded may require an explicit wait.
Understanding how Selenium WebDriver locates elements and how JavaScript accesses the DOM gives you a strong foundation for web automation testing.
Next, we will look at Shadow DOM in Selenium, including how a shadow root works and why some elements in modern web applications cannot be located using ordinary DOM locators alone.
What Is Shadow DOM in Selenium?
So far, we have learned how Selenium WebDriver locates elements in the regular DOM and interacts with them during automation testing. However, modern web applications sometimes use a different structure called the Shadow DOM. When this happens, locating an element may require an additional step.
Shadow DOM is a web browser feature that allows developers to keep the internal structure of a component separate from the main DOM tree. It is commonly used in web components, where a part of a web page has its own HTML elements, styles, and behavior.
For example, a website may use a custom search component, date picker, or video player. The component may contain input fields and buttons inside its Shadow DOM. Although the component appears as part of the web page, its internal elements are organized within a separate shadow tree.
This difference is important when using Selenium. A regular locator such as driver.findElement() searches the elements available through the regular DOM. To locate elements inside an open Shadow DOM, you generally need to find the shadow host, access its shadow root, and then search within that root.
Before learning how to handle Shadow DOM elements using Selenium, let’s understand what a shadow root is, how it differs from the regular DOM, and the difference between open and closed Shadow DOM.
What Is a Shadow Root and How Does It Work?
A shadow root is the root of a separate DOM tree attached to an element called the shadow host. The shadow host belongs to the main DOM, while the elements inside its Shadow DOM belong to the separate shadow tree.
In simple words, the shadow host is the main element that contains the component, and the shadow root provides access to the component’s internal DOM structure when the component uses an open Shadow DOM.
Consider this example:
<my-search></my-search>
Here, my-search is a custom HTML element that can act as a shadow host. Its internal structure might contain a search input and a button, even though those elements do not appear directly in the original HTML markup.
A developer could create this structure using JavaScript:
const host = document.querySelector("my-search");

const shadowRoot = host.attachShadow({ mode: "open" });

shadowRoot.innerHTML = `

    <input id="searchBox" type="text">

    <button id="searchButton">Search</button>

`;
In this example, JavaScript attaches an open Shadow DOM to the my-search element. The input field and button are added inside the shadow root rather than directly to the main DOM tree.
The structure can be understood as follows:
- Main DOM: Contains the my-search element.
- Shadow host: The my-search element that holds the component’s Shadow DOM.
- Shadow root: The root through which the component’s internal DOM can be accessed in open mode.
- Shadow tree: Contains the search input and button inside the component.
The key point is that the input and button are inside the shadow tree, not directly inside the regular DOM tree. This is why you need to access the shadow root before locating those elements with Selenium.
Difference Between the Regular DOM and Shadow DOM
The regular DOM and Shadow DOM both represent HTML elements as connected nodes. However, they serve different purposes when developers build web pages and reusable components.
The regular DOM represents the main document structure. The Shadow DOM provides a separate tree for the internal structure of a component, helping developers keep its styles and internal elements separate from the surrounding page.
Here are the main differences:
| Regular DOM | Shadow DOM |
| Represents the main document structure. | Represents the internal structure of a component. |
| Elements belong to the main DOM tree. | Elements belong to a separate shadow tree. |
| Elements can usually be located through ordinary WebDriver locators when available. | Elements generally require access to the relevant shadow root. |
| Styles may affect elements according to normal CSS rules and scope. | Styles are scoped differently, helping isolate component styling. |
| Does not require a shadow host to access ordinary elements. | Is attached to a host element. |
For example, consider a normal input field:
<input id="username" type="text">

You can locate this element directly using Selenium:

WebElement username =

    driver.findElement(By.id("username"));
Now imagine the input field is inside an open Shadow DOM. You must first locate its host and access the shadow root before finding the input field.
WebElement host =

    driver.findElement(By.cssSelector("my-search"));

SearchContext shadowRoot = host.getShadowRoot();

WebElement searchBox =

    shadowRoot.findElement(By.id("searchBox"));
In this example, my-search is the shadow host, and searchBox is an element inside its shadow tree.
Understanding this difference helps you choose the correct locator strategy. It also makes it easier to troubleshoot situations where an element is visible on the web page but cannot be found through a normal Selenium locator.
What Are Open Shadow DOM and Closed Shadow DOM?
Shadow DOM has two modes: open and closed. The mode determines how the shadow root can be accessed through the standard DOM API.
Both modes allow developers to create a separate DOM tree for a component. The main difference is whether the shadow root is exposed through the host element’s shadowRoot property.
1. Open Shadow DOM
An open Shadow DOM allows the shadow root to be accessed through the host element’s shadowRoot property in JavaScript.
For example:
const host = document.querySelector("my-search");

console.log(host.shadowRoot);
If my-search has an open Shadow DOM, this code returns its shadow root. Selenium WebDriver also provides the getShadowRoot() method to access an exposed shadow root.
Open Shadow DOM is generally straightforward to handle in Selenium because you can locate the host, access its shadow root, and find the required elements inside it.
2. Closed Shadow DOM
A closed Shadow DOM does not expose its shadow root through the host element’s standard shadowRoot property.
For example:
const host = document.querySelector("my-search");

const shadowRoot = host.attachShadow({ mode: "closed" });

console.log(host.shadowRoot);
In this case, host.shadowRoot returns null because the component uses closed mode.
This does not mean that the component’s internal elements cannot function. They can still work normally as part of the web page. However, the standard method used to access an open shadow root is not available through the host.
For Selenium automation, this creates an important limitation. The standard getShadowRoot() method cannot retrieve a closed shadow root through the usual host-element API. Testing such components may require a supported testing interface, changes to the component’s design, or assistance from the development team.
Why does this matter in Selenium?
Before writing your automation script, you should identify whether the required element belongs to the regular DOM or a Shadow DOM. If it belongs to an open Shadow DOM, Selenium can access it through the shadow root. If it belongs to a closed Shadow DOM, the standard approach will not work in the same way.
Now that you understand how Shadow DOM works, the next step is to learn how to handle Shadow DOM elements using Selenium WebDriver, including how to locate the shadow host and interact with elements inside an open shadow tree.
How to Handle Shadow DOM Elements Using Selenium
Now that you understand the difference between the regular DOM and Shadow DOM, let’s learn how to work with Shadow DOM elements using Selenium WebDriver.
In modern web applications, some elements are placed inside a shadow tree instead of the main DOM tree. For example, a custom search box may contain an input field and a Search button inside its Shadow DOM. Although these elements appear on the web page, Selenium may not be able to locate them directly using a regular locator.
To interact with these elements, you need to locate the shadow host, access the shadow root, and then find the required element inside it. Selenium WebDriver provides the getShadowRoot() method for accessing an exposed shadow root.
Let’s explore how this works with practical Java examples.
How to Locate an Open Shadow Root Using Selenium WebDriver
To locate an element inside an open Shadow DOM, you must first identify its shadow host. The shadow host is the HTML element to which the Shadow DOM is attached.
After finding the host, you can use Selenium WebDriver’s getShadowRoot() method to access the shadow root. You can then search for the required element inside that root.
Consider the following HTML structure:
<my-search></my-search>
Suppose the my-search element contains an open Shadow DOM with a search input and a button. You can locate these elements using the following Java code:
WebDriver driver = new ChromeDriver();

driver.get("https://example.com");

WebElement shadowHost =

    driver.findElement(By.cssSelector("my-search"));

SearchContext shadowRoot =

    shadowHost.getShadowRoot();

WebElement searchBox =

    shadowRoot.findElement(By.cssSelector("#searchBox"));

searchBox.sendKeys("Selenium WebDriver");
Here is what each step does:
- driver.findElement() locates the my-search element in the main DOM.
- getShadowRoot() accesses the host’s exposed shadow root.
- shadowRoot.findElement() locates the search input inside the shadow tree.
- sendKeys() enters the search text into the input field.
In this example, my-search and #searchBox are sample selectors. You must replace them with the actual shadow host and element selectors from the web page you are testing.
Important: This approach works when the host has an accessible shadow root, such as an open Shadow DOM. If the component has not loaded yet, you may also need an explicit wait before locating the host or accessing the element.
How to Find an Element Inside Shadow DOM Using Java
Sometimes, you need to locate an element inside Shadow DOM and perform an action such as clicking a button or entering text. Selenium WebDriver allows you to do this by using the SearchContext interface returned by getShadowRoot().
Consider a custom login component that contains a username field and a Login button inside its open Shadow DOM.
You can use the following example:
WebElement shadowHost =

    driver.findElement(By.cssSelector("login-component"));

SearchContext shadowRoot =

    shadowHost.getShadowRoot();

WebElement username =

    shadowRoot.findElement(By.cssSelector("#username"));

WebElement loginButton =

    shadowRoot.findElement(By.cssSelector("#loginButton"));

username.sendKeys("testuser");

loginButton.click();
In this example, Selenium first locates the login-component host in the main DOM. It then accesses the shadow root and finds the username field and Login button inside the component.
After locating both elements, Selenium enters the username and clicks the button.
Notice that shadowRoot.findElement() is used instead of driver.findElement() for the elements inside the Shadow DOM. This is because the search must take place within the shadow root rather than the main document.
You can also locate an element using its class name, tag name, or another supported locator:
WebElement input =

    shadowRoot.findElement(By.cssSelector("input"));

WebElement button =

    shadowRoot.findElement(By.cssSelector("button"));
However, make sure your locator identifies the intended element. If the shadow tree contains multiple input fields or buttons, a more specific selector will help you find the correct one.
How to Handle Nested Shadow DOM Elements
Some modern web applications contain more than one Shadow DOM nested inside another component. In such cases, an element may be located inside a second shadow tree rather than directly inside the first shadow root.
For example, imagine the following structure:
- The main DOM contains a user-panel element.
- The user-panel has an open Shadow DOM.
- Inside that shadow tree, there is a login-component element.
- The login-component has its own open Shadow DOM.
- The username field is inside the second shadow tree.
You must access each shadow root in order, moving from the outer component to the inner component.
Here is how you can do this using Java:
WebElement outerHost =

    driver.findElement(By.cssSelector("user-panel"));

SearchContext outerRoot =

    outerHost.getShadowRoot();

WebElement innerHost =

    outerRoot.findElement(

        By.cssSelector("login-component")

    );

SearchContext innerRoot =

    innerHost.getShadowRoot();

WebElement username =

    innerRoot.findElement(

        By.cssSelector("#username")

    );

username.sendKeys("testuser");
Let’s understand the process:
- Selenium locates the user-panel in the main DOM.
- It accesses the first shadow root using getShadowRoot().
- It locates the login-component inside the first shadow tree.
- It accesses the second shadow root.
- It finds the username field inside the second shadow tree and enters the text.
Each shadow root creates a separate search context. Therefore, you cannot skip an intermediate shadow root when locating an element nested inside it.
The example assumes that both components use accessible shadow roots. If the page contains more nested components, you can repeat the same process for each level.
When working with nested Shadow DOM, inspect the component structure carefully before writing your Selenium test. This helps you identify the correct shadow hosts and reduces element-location errors.
Can Selenium Access Closed Shadow DOM Elements?
Selenium WebDriver’s standard Shadow DOM methods are designed to work with shadow roots that the browser exposes through its supported interfaces. A closed Shadow DOM does not expose its root through the host element’s standard shadowRoot property.
For example, the following JavaScript returns null when the host uses a closed Shadow DOM:
const host = document.querySelector("my-component");

console.log(host.shadowRoot);
Because the root is not exposed through this property, the standard Selenium approach using getShadowRoot() cannot retrieve that closed root through the host element.
This does not mean that every component using closed Shadow DOM is impossible to test. The right approach depends on how the component is built and what testing support is available.
Here are some practical options:
- Ask the development team: They may provide test-friendly attributes, public component methods, or a supported testing interface.
- Test through public behavior: If the component can be operated through visible controls, focus on the behavior available to a real user.
- Use a supported component API: Some applications provide a documented way to interact with the component without accessing its internal shadow tree.
- Avoid relying on internal browser workarounds: Such approaches may be fragile and may not work consistently across browsers or Selenium versions.
For reliable automation testing, prefer testing the component through its intended user-facing behavior or an officially supported testing interface rather than depending on access to its private internal structure.
Understanding these methods will help you handle Shadow DOM elements more confidently in Selenium WebDriver. However, locating elements is only one part of writing maintainable tests. The next section explains the Page Object Model in Selenium and how it helps organize web elements and automation code.
What Is the Page Object Model in Selenium?
So far, we have learned how Selenium WebDriver locates elements in the DOM, interacts with HTML elements, and handles Shadow DOM. As your automation testing project grows, you may need to test many web pages, each containing several buttons, forms, links, and other elements.
If you write all your locators and test actions in a single class, your code can become difficult to manage. For example, if a Login button’s ID changes, you may need to update several test scripts that use that button. This is where the Page Object Model (POM) becomes useful.
The Page Object Model is a design pattern used in Selenium automation to organize web pages and their related elements into separate classes. It helps keep element locators and page actions separate from the main test logic, making your code easier to maintain and reuse.
It is important to understand that the DOM and the Page Object Model serve different purposes. The DOM represents the structure of a web page, while the Page Object Model organizes the code you write to interact with that page.
Let’s look at how POM works, how it organizes web elements, and how it relates to DOM-based Selenium automation.
How the Page Object Model Organizes Web Elements
The Page Object Model organizes the elements and actions of a web page into a dedicated class. Instead of repeating the same locators in multiple test scripts, you define them in one place and create methods for common actions.
For example, imagine you are testing a login page. Your test needs to enter a username, enter a password, and click the Login button.
Without the Page Object Model, you might write all these locators and actions directly inside the test class. If you have several login tests, the same code may appear repeatedly.
With POM, you can create a LoginPage class to manage the username field, password field, and Login button.
Example: LoginPage.java

public class LoginPage {

    WebDriver driver;

    By username = By.id("username");

    By password = By.id("password");

    By loginButton = By.id("login");

    public LoginPage(WebDriver driver) {

        this.driver = driver;

    }

    public void enterUsername(String value) {

        driver.findElement(username).sendKeys(value);

    }

    public void enterPassword(String value) {

        driver.findElement(password).sendKeys(value);

    }

    public void clickLogin() {

        driver.findElement(loginButton).click();

    }

}
In this example, the LoginPage class stores the locators and provides methods to interact with the login page. These locators identify elements in the DOM, while the methods describe the actions Selenium should perform.
You can then use this class in a test:
LoginPage loginPage = new LoginPage(driver);

loginPage.enterUsername("testuser");

loginPage.enterPassword("password123");

loginPage.clickLogin();
The test code is now easier to read because it focuses on what the test needs to do rather than repeating the details of each element locator.
If the username field’s ID changes, you can update the locator in the LoginPage class instead of searching through every test script that uses it.
This separation helps you maintain your Selenium automation code as the application grows.
Difference Between the DOM and Page Object Model
Although the DOM and Page Object Model are both important in Selenium automation, they are not the same thing.
The DOM is created by the browser when it processes a web document. The Page Object Model is a design pattern that developers and testers use to organize their automation code.
Here are the main differences:
| DOM | Page Object Model |
| Represents the structure of a web document. | Organizes Selenium automation code. |
| Contains elements such as buttons, forms, links, and input fields. | Contains page classes, locators, and methods for page actions. |
| Is managed by the browser and can change when the page updates. | Is designed and maintained by the automation tester. |
| Helps Selenium identify elements through supported locators. | Helps testers reuse locators and actions across test cases. |
| Exists as part of the browser’s representation of the page. | Exists as part of the test automation project’s code. |
For example, when the browser loads a login page, it creates the DOM containing the username field and Login button. Selenium can locate these elements using their IDs.
The Page Object Model allows you to store those locators and the related actions inside a LoginPage class.
Therefore, the DOM provides the structure that Selenium interacts with, while POM provides a way to organize the code used to interact with that structure.
How DOM Elements Are Used in Selenium Test Automation
DOM elements are the actual page elements that Selenium locates and interacts with during a test. These include text fields, buttons, checkboxes, dropdowns, links, and other HTML elements.
In a typical Selenium test, the browser loads a web page and creates its DOM structure. Selenium WebDriver then uses locators to find the required elements and perform actions. Your test script checks whether the application behaves as expected.
For example, consider a login test:
- Open the login page in the browser.
- Locate the username field using its ID.
- Enter the username.
- Locate the password field and enter the password.
- Locate the Login button and click it.
- Verify whether the expected page or success message appears.
When you use the Page Object Model, you can place the locators and actions inside the relevant page class while keeping the test steps in a separate test class.
This approach becomes especially useful when an application contains many pages or when several test cases use the same web elements.
You should also remember that DOM elements can change while a test is running. For example, JavaScript may update a button, replace a form, or display a message after a user action. Your page objects and test scripts should account for these changes by using reliable locators, suitable waits, and fresh element lookups when necessary.
For components that use Shadow DOM, you can also organize the shadow host, shadow root access, and element-location logic within an appropriate page object. This keeps the Shadow DOM handling separate from the main test logic.
In short, combining DOM knowledge with the Page Object Model helps you write Selenium tests that are easier to understand, reuse, and maintain.
However, even when your locators and page objects are well organized, your tests may still fail because of dynamic DOM changes, incorrect locators, or elements that are not yet available. In the next section, we will explore common DOM-related errors in Selenium automation and how to handle them.
Common DOM-Related Errors in Selenium Automation
Even when you understand the DOM structure and use the correct Selenium WebDriver methods, you may still face errors during automation testing. These errors often occur when an element cannot be found, the page changes while the test is running, or an element inside a Shadow DOM is accessed incorrectly.
For example, a button may appear on the web page, but Selenium may fail to locate it because the page has not finished loading. Similarly, a JavaScript update may replace an element after Selenium has already found it.
Understanding these problems helps you identify the cause of a failed test and choose the right solution. Let’s look at some common DOM-related errors and the best ways to handle them.
NoSuchElementException When Locating DOM Elements
NoSuchElementException occurs when Selenium WebDriver cannot find an element using the locator you provided. This may happen because the locator is incorrect, the element has not loaded yet, or the element is inside a Shadow DOM that you have not accessed.
For example, consider the following HTML:
<input id="username" type="text">

You can locate the username field using its ID:

WebElement username =

    driver.findElement(By.id("username"));

However, if you accidentally use the wrong ID, Selenium cannot find the element.

WebElement username =

    driver.findElement(By.id("userName"));
In this example, the locator uses userName, but the actual ID is username. Since IDs are case-sensitive, Selenium does not find a matching element.
How to fix this error:
- Check the element’s ID, name, class, CSS selector, or XPath in the browser’s Developer Tools.
- Confirm that the element is present in the current DOM.
- If the element loads after a delay, use an explicit wait.
- If the element belongs to a Shadow DOM, locate the shadow host and access the appropriate shadow root first.
For elements that appear after a delay, you can use an explicit wait:
WebDriverWait wait = new WebDriverWait(

    driver, Duration.ofSeconds(10)

);

WebElement username = wait.until(

    ExpectedConditions.visibilityOfElementLocated(

        By.id("username")

    )

);
This code waits up to 10 seconds for the username field to become visible. If the element becomes visible earlier, Selenium continues without waiting for the full duration.
Remember that a wait cannot fix an incorrect locator. Always confirm that the locator matches the intended element before increasing the wait time.
StaleElementReferenceException After DOM Updates
StaleElementReferenceException occurs when Selenium holds a reference to an element that is no longer attached to the current DOM or no longer represents the same element.
This often happens when JavaScript updates a page, replaces a form, refreshes a section, or changes the elements after a user action.
For example:
WebElement button =

    driver.findElement(By.id("submit"));

// The page updates and replaces the button.

button.click();
If the original button has been removed or replaced before click() executes, Selenium may throw a StaleElementReferenceException.
How to fix this error:
Locate the element again after the DOM changes. You can also use an explicit wait to wait for the updated element to become available.
WebDriverWait wait = new WebDriverWait(

    driver, Duration.ofSeconds(10)

);

WebElement button = wait.until(

    ExpectedConditions.elementToBeClickable(

        By.id("submit")

    )

);

button.click();
This example waits for the element matching the locator to become clickable and then clicks it.
However, elementToBeClickable() does not guarantee that the element will remain unchanged until the click occurs. If the application frequently replaces elements, you may need to locate the element again or handle the stale reference when appropriate.
The key lesson is to avoid keeping old WebElement references when the page is likely to replace the underlying elements.
Common Shadow DOM Element-Location Problems
When working with Shadow DOM, Selenium may fail to locate an element even when that element appears on the web page. This usually happens because the element belongs to a separate shadow tree rather than the main DOM.
For example, consider a custom component with an open Shadow DOM containing a search input. The following code may fail because Selenium is searching the main DOM:
WebElement searchBox =

    driver.findElement(By.id("searchBox"));

If the input is inside a shadow tree, you should first locate the shadow host and access its shadow root.

WebElement host =

    driver.findElement(By.cssSelector("my-search"));

SearchContext shadowRoot = host.getShadowRoot();

WebElement searchBox =

    shadowRoot.findElement(By.id("searchBox"));
Here, my-search and searchBox are example selectors. Replace them with the actual selectors from your web application.
Other common Shadow DOM problems include:
- Incorrect shadow host: The selector does not identify the component that owns the required shadow tree.
- Nested Shadow DOM: The element is inside another shadow root, so you must access each shadow host and root in order.
- Delayed component loading: The shadow host or its internal elements are not available when Selenium tries to locate them.
- Closed Shadow DOM: The component does not expose its shadow root through the standard API, so getShadowRoot() cannot access it through the usual method.
To troubleshoot these problems, inspect the component in Developer Tools, confirm the shadow host, check whether the root is accessible, and verify the element’s selector. For dynamic components, use suitable waits and locate elements after they become available.
Best Practices for Reliable Web Testing
Understanding the DOM is useful, but following good automation practices is equally important. A reliable Selenium test should work with the page’s current structure, handle expected changes, and use locators that are easy to maintain.
Here are some practical ways to improve your web testing.
1. Use Reliable Locators
Choose unique IDs or stable attributes whenever possible. If you use CSS selectors or XPath, make sure they identify the intended element without depending on unnecessary details of the DOM structure.
2. Use Explicit Waits
Some elements appear only after JavaScript runs or data loads. Use explicit waits to wait for the required condition instead of relying on fixed delays.
3. Locate Elements After DOM Changes
If an application replaces an element, locate it again before performing the next action. This helps avoid stale element references.
4. Inspect the Current DOM
When an element cannot be found, use browser Developer Tools to inspect the current DOM. Do not rely only on the original HTML source, because JavaScript may have added or changed elements.
5. Handle Shadow DOM Correctly
Locate the shadow host, access its exposed shadow root, and then search for the element inside it. For nested Shadow DOM, repeat this process for each level.
6. Use the Page Object Model
Organize page locators and actions into separate page classes. This reduces repeated code and makes it easier to update locators when the application changes.
7. Prefer Real User Interactions
Use normal WebDriver methods such as click() and sendKeys() for common user actions. Use JavaScript execution when there is a clear testing need, rather than using it to bypass problems that a real user would face.
8. Keep Tests Focused and Maintainable
Use clear method names, meaningful assertions, and reusable helper methods. When a test fails, make sure the error message and logs help you identify whether the problem comes from a locator, timing issue, DOM update, or Shadow DOM access.
Following these practices can help you write more stable Selenium automation tests and reduce failures caused by changes in the DOM.
Next, let’s answer some frequently asked questions about DOM in Selenium, including how Selenium interacts with HTML, how JavaScript helps locate elements, and how to handle Shadow DOM.
Frequently Asked Questions About DOM in Selenium
What Is DOM in Selenium WebDriver?
DOM in Selenium refers to the Document Object Model that the browser creates to represent a web page’s structure. Selenium WebDriver uses locators such as ID, name, CSS selectors, and XPath to find elements in the page’s DOM and interact with them. Understanding the DOM helps you write better automation scripts and troubleshoot element-location problems.
Does Selenium Interact Directly With HTML or the DOM?
Selenium WebDriver interacts with web pages through browser-supported WebDriver commands. The browser processes the HTML and creates the DOM, which represents the page’s elements and structure. Selenium uses this browser interface to locate elements and perform actions such as clicking buttons, entering text, and reading content.
Can JavaScript Be Used to Locate DOM Elements in Selenium?
Yes, you can use JavaScript through Selenium’s JavascriptExecutor interface to access DOM elements and read their properties or content. For example, you can use JavaScript’s document.getElementById() method to find an element. However, Selenium’s built-in locator methods are generally preferred for normal element interactions.
How Do You Find Elements Inside an Open Shadow DOM?
To find elements inside an open Shadow DOM, first locate the shadow host using Selenium WebDriver. Then call getShadowRoot() to access its shadow root and use findElement() to locate the required element inside it.
For example:
WebElement host =

    driver.findElement(By.cssSelector("my-component"));

SearchContext shadowRoot = host.getShadowRoot();

WebElement element =

    shadowRoot.findElement(By.cssSelector("#target"));
Replace my-component and #target with the actual selectors from your web page.
What Is the Difference Between DOM and Shadow DOM?
The regular DOM represents the main structure of a web page, while Shadow DOM provides a separate tree for the internal elements of a component. Selenium can usually locate regular DOM elements directly, but accessing elements inside an open Shadow DOM generally requires finding the shadow host and accessing its shadow root.
Can Selenium Automate Elements Inside a Closed Shadow DOM?
Selenium’s standard getShadowRoot() method cannot access a closed Shadow DOM through the host’s usual exposed shadow-root interface. However, testing may still be possible through public component behavior, supported testing interfaces, or changes provided by the development team. The best approach is to test the component through its intended behavior rather than relying on fragile internal workarounds.
Final Thoughts
Understanding the DOM in Selenium helps you learn how a browser organizes HTML elements and how Selenium WebDriver locates and interacts with elements on a web page. From learning the DOM structure to using JavaScript and handling Shadow DOM, these concepts help you write better automation test scripts and solve common testing problems.
If you want to build your skills in Selenium with Java, regular practice with real-time projects can help you gain confidence in automation testing. Payilagam helps learners develop practical software skills through hands-on training and project-based learning. If you are searching for the Best Selenium Training in Chennai or the Best Software Training Institute in Chennai, Payilagam is an option to explore for practical learning and guidance.
Start learning Selenium step by step, practise with real web applications, and strengthen your automation testing skills to prepare for opportunities in the IT industry.